Context Layer for AI Agents: Sourced Answers and Human-Approved Actions Across Chat, Tickets, Wiki and CRM
Your team searches chats, tickets and CRM for the latest customer status and still has to ask colleagues what was actually decided. I build context layers for AI agents that connect this information: like a shared handover log with sources and timestamps. Colleagues with the right permissions can trace decisions, even if they missed the meeting. Actions in other systems require approval.
Problem: The company did not have one current state of a customer. It had five: the ticket board, the wiki page, the chat thread, the CRM deal and the meeting that overruled all four. Knowing what moved meant checking six systems, or hearing about it two days later.
Solution: One governed layer on the company's own cloud tenant. It reads every source as the person asking, folds the changes per customer, cites the passage behind every item, and lets a named person approve every action before anything is written. Sharing is automatic: a person switches it on once, and every decision from their meetings reaches the teams it concerns within minutes, with nothing to do per meeting.
Business value: Knowledge said in a meeting or on a call is shared as a signed fact with exactly the team it concerns. Someone who was not in the meeting learns what was decided without asking anyone who was. A change radar replaces six morning checks. Every write into tickets, the wiki or chat is one a person approved, with the receipt on the card, so an audit reads the decision, not a log.
Frame: Architecture review of your agents' write path first, in a set number of hours, then a phased build on your tenant, billed by the hour. Compute, storage and model inference in the EU.
Read the video transcript
Pulse brings the changes that matter into one dashboard, with the source and reason on every item.
The Action Inbox separates work that needs a decision from work ready to run, and records every result.
The Proposals tab turns candidate claims into governed facts. The owner can edit the wording, choose who may read it, and mark it true.
One note can mention several topics. The mapper links each fact to the correct customer, product, or policy record, and leaves uncertain matches unassigned.
After approval, facts appear automatically for the allowed team. Facts from personal sources still need a manual sharing decision.
This creates one governed path from change, to action, to shared knowledge. We can map the first workflow in an architecture review.
The problem
A DACH B2B technology company runs enterprise customer projects. Each customer lives in six places at once: a ticket board, a wiki space, a chat channel, a CRM deal, several mailboxes and the meetings where the real decisions are taken. Stakeholders across sales, delivery, engineering, operations and management were interviewed before the first line of code. Their questions, condensed:
- Which of the five states of this customer is current, and who decided that?
- What changed since I last looked that I probably missed?
- Can I trust an answer, or do I have to open the source anyway?
- Can the system act on a change, and who is accountable when it does?
- What may a colleague see of my meetings and my deals, and what may an assistant see?
- Will any of this survive a security review?
The company already had digests. The chat suite summarises messages and mail per person, the wiki suite summarises pages and tickets per person. Neither cites the passage that put an item in front of you, neither carries a colleague’s signature, neither writes back into the record, and neither knows which customer a page, a thread and a ticket belong to. That gap is the whole engagement.
This case study is written for CTOs, VPs of Engineering and heads of IT in DACH companies that need a context layer for their AI agents: a permission-aware assistant with sourced answers and human-approved actions across chat, tickets, wiki and CRM on their own EU cloud tenant, built on a temporal knowledge graph that keeps every fact with its source and the time it held. The offer behind it is knowledge graph consulting.
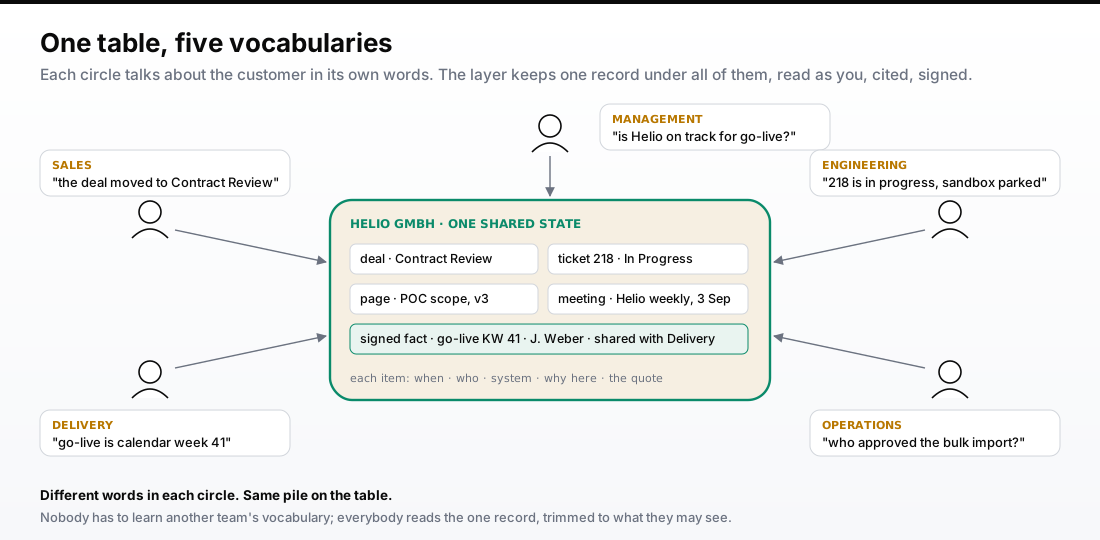
One table, five vocabularies. Each circle talks about the customer in its own words; the layer keeps one record under all of them, read as you, cited, signed.
The solution
An operational context layer on the company’s own tenant. It solves the three things every operational-intelligence platform has to solve, and it stays small while doing it: typed records, delegated reads, and human authorization before external actions.
An operational context layer is a permission-aware layer across a company’s systems of record (chat, tickets, wiki, CRM, mailbox, meeting notes) that decides which item is current and for whom, cites the passage behind every item, and turns it into an action a named person approves.
1. One model of the business
- A customer registry that everything folds under. A page, a thread, a ticket, a deal and a meeting all belong to a customer, and the layer knows which one. That is the question no single system answers, and it is the first thing the model settles.
- Every record is typed and carries where it came from. System, record, author, date and the quoted passage travel with it.
- Facts as relations, proven per row. A claim enters the graph only as a relation the review can check (customer, go-live, calendar week 41), signed by a person, with the record it came from.
2. Context that knows who is asking
- Read as you. The layer holds no permissions of its own. Every read of chat, mailbox, meeting transcripts, tickets, wiki and CRM runs delegated, as the signed-in person, and membership comes from the company’s own directory groups at question time.
- Trimmed, cited, or not shown. An answer is cut to what the asker may see, every item cites the passage behind it, and a hit the asker may not open is dropped without a count.
- Shared automatically, by consent, per audience. A person switches sharing on once; from then on every decision from their meetings reaches the team it concerns within minutes, and nobody else, with nothing to do per meeting. The chain under it says where to look, never how much to believe a colleague.
3. Actions a person owns
- The Proposals tab is the action inbox. Every proposed fact and every proposed action waits there for the person’s verdict, one row at a time, posted as a card in chat. A review stays open until a person decides it; a lost card or a missed message never closes one.
- Act where the change lives, as yourself. A comment on the ticket, an append to the wiki page, a reply into the chat thread, a work item on the board. The receipt stays on the card.
- One backend, every door. The chat bot and tabs for people; an MCP door that plugs the same governed backend into Claude (Cowork, Desktop and the claude.ai connector), Codex and any MCP-enabled application. Same stores, same gate, same audit events, so adoption is measurable per door from day one.
"deprioritised the sandbox until Helio confirms the go-live window"
Synthetic screenshot 1: the change radar, with fictional customers, people and records. Each item says when, who, which system, why it is on your radar, and quotes the mention. The signed fact carries its chain: signer first, the meeting it came from, who it is shared with, how many independent sources back it.
What the person sees
The screenshots on this page are synthetic. They show the real screens with fictional customers, people and records, so the client stays unnamed and no record leaves the tenant.
Capabilities
What people use it for, in the order they adopted it:
- The change radar. What changed since I last looked that matters to me, folded per customer, with the mention cited or the item dropped. A day at minimum, seven at most, so time away is caught up rather than silently dropped. A source that did not answer is named on the page, so a quiet radar and a failed read are different things.
- The morning brief. The same radar as one short text at the start of the day, counting a fact as news when it reached the graph, not only when it became true.
- Call notes to decisions. Meeting transcripts are read live as the person and written up: notes, decisions, who agreed to do what. The decisions land in the person’s Proposals tab one row at a time. Sharing the write-ups with a colleague shows them the write-up, never the transcript.
- Grounded questions. Ask about a customer, a page, a decision. The answer cites its sources, is trimmed to what the asker may see, and says “not found” rather than inventing.
- Write-backs as yourself. Comment on the ticket, append to the wiki page (never replace, so inline comments stay anchored), reply in the chat thread, create a work item. Every one approved on a card, every one with a receipt.
- The deal next to the work. CRM stage and close date beside the engineering movement, the question no single system answers.
- The editor door. The same backend over MCP inside Claude (Cowork, Desktop, the claude.ai connector), Codex and any MCP-enabled application. Same identity, same gate, same audit trail.
something is said, or something changes in a system
  -> a person says true, or a person approves
  -> it lands, cited, for the people it concerns
  -> actions go back into the systems as the person, with a receipt
"Helio asked whether the ordering interface can take a bulk import before go-live, they have 1,200 legacy items"
Synthetic screenshot 2: the human gate. A proposal is staged as pending and posted as a card. The same message can never open a second review; a decline is itself an audited decision.
Synthetic screenshot 3: the Proposals tab, the action inbox. One row per claim, one verdict per row. A claim that makes no checkable relation is refused with the row still pending. An assistant may propose into this queue and may not accept.
Control guarantees
The differentiator is not the model. It is what the layer refuses to do:
- Delegated permissions only. No service account with everything. A person sees what they would see anyway, an assistant sees what its user sees.
- Proposed external actions require approval before execution. This includes MCP. An assistant can propose and cannot accept. Fact sharing follows its separately recorded individual or scoped standing consent.
- Never asked twice. The same message never opens a second review, and the same signal from a second message never does either; a decline and a dedup are audited decisions.
- A review stays open until a person decides it. A lost card or a missed message never closes one, and two people never work the same row.
- Provenance on every record, the mention cited or the item dropped. Reason, verbatim passage, author, link.
- Rings rank sources, never people. Which system a conflicting answer should follow is shown; no grade, badge or score ever sits on a colleague.
- HR and personal data excluded in depth. Commercial terms and anything about employment never travel, even when sharing is on. Meetings with an external participant are refused. Transcripts are never stored.
- Append-only audit trail, including declined and deduplicated items. Rollback of a confirmed action is compensation, never deletion. Every fact is removable.
- Gap telemetry from day one. The company sees which questions the layer could not answer, per source, so value is measured per system and never per person.
- Data residency stated precisely. Compute, storage and language-model inference in the EU, on the company’s own cloud tenant: OpenAI models in Azure AI Foundry, processed only inside the EU, each model named with its deployment.
Guardrail
The layer never rewrites production behaviour from one session. A shared fact enters through a human verdict or scoped standing consent; an external action enters through its approval gate, and the audit trail keeps the declined and the deduplicated next to the confirmed. When two sources disagree, the ring says which system to follow and the chain says where to look. Nobody meets a dossier by default, and anybody can jump one hop to the record instead of sending a colleague a message.
The approval pattern behind this gate, a proposal staged as pending and a person’s approval before executing the proposed external action, is documented in the Human-in-the-Loop Approval Flow Blueprint.
Five capabilities this proves
- Permission-aware answers across six systems without a service account.
- A human gate that holds on every door, including the one an assistant uses.
- Provenance that survives into the radar, the brief and the answer.
- Write-backs into the systems of record as the person, with a receipt.
- A knowledge graph that people fill through verdicts, and that pays back on the radar.
Automatic sharing: the knowledge graph on the radar
The graph holds what no system holds. A decision taken in a meeting, a constraint said on a call, a correction typed in a chat: none of it lives in a ticket, a page or a deal record. The layer turns it into a signed fact with the record it came from, shares it automatically with exactly the team it concerns, and puts it on their radar within minutes, with nothing for anyone to send. That is sharing information without building a system for it, and it is the top value the graph has proven.
Which proposals need a verdict at all, and which a rule can carry without a click, is the routing question worked through in which agent memory writes never need a human.
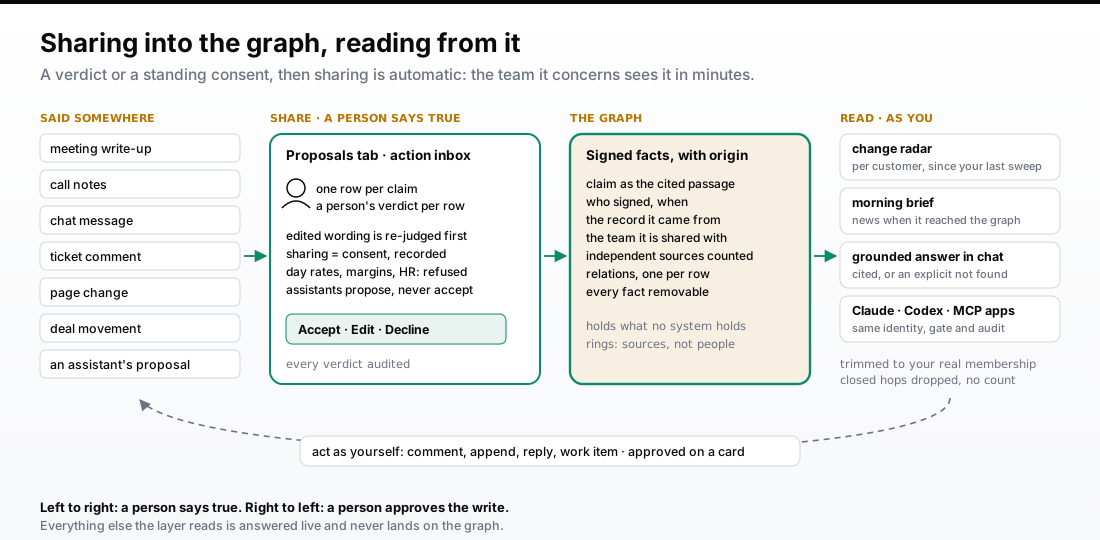
Left to right: a person says true. Right to left: a person approves the write. Everything else the layer reads is answered live and never lands on the graph.
The latest step puts the graph itself on the radar, the part no digest has:
- A colleague’s signed fact reaches the team’s radar within minutes. When a person accepts a fact and shares it with a team, everyone in that team sees it under the customer it names: the claim as the cited passage, who signed it, the team it was shared with. Membership is read as each person, so a team’s fact reaches its members and nobody else, and your own facts are not news to you.
- Where it came from, in one line. Under each item: the record it came from, who filed it, who said true to it and when, how many independent sources back it. Signer first, the meeting or mail it came from, the link to the write-up. The full chain opens on tap. It is shown as where to look, never as how much to believe.
- The test that counts. Somebody who was not in a meeting learns what was decided there without asking anybody who was. That is the sentence people use to describe the value.
- A ticket line says what moved, not where the ticket stands. “Status To Do → In Progress”, read from the change history at no extra cost. A bulk edit is one card, with the rows behind it on tap.
- Under each customer, where its changes came from. “Tickets 7 · Wiki 2 · Your mailbox 1”, the fold made visible, and a line no single system’s digest can print.
- One way onto the graph. A fact reaches the graph only through a person’s verdict or a person’s standing consent. Nothing the layer merely reads ever lands on it.
What we measured
| Item | Reading |
|---|---|
| Sources folded on one radar | 6 (chat, tickets, wiki, CRM, mailbox, meeting notes) |
| External actions without authorization | 0, by construction, on every door |
| Reviews opened twice for one signal | 0, by construction |
Honest status
In production on the client’s own tenant. Adoption is measured from audit events per door, never from opinions.
Request the architecture review
This page shows the operating model and the guarantees. The detailed architecture behind it stays off the page on purpose: identity resolution, permission mapping, authority, recency and supersession rules, the schemas, prompts and tool orchestration, the connector and deployment code.
The way in is a review of the write path of the agents you already run, in a set number of hours: your routing rules, the measured ratio of what reaches a human today versus what should, and the three rules that pull that number down. You get the review as a document you can hand to your security and procurement people. The architecture walk-through follows the review, once we know who is asking and what for.
The review is the AI Pilot to Production Audit; the 30-minute architecture call is the free first step. The full operating model, the ten guarantees and a self-check for your security review are on the agent control page.
Try one context-to-action workflow
The Palantir Foundry alternative guide includes a separate MIT-licensed starter with fictional records, a Python SDK and an approval-to-receipt walkthrough. It shows one local workflow you can inspect and extend.
Frequently asked questions
What is an operational context layer, compared to enterprise search or a Copilot?
Enterprise search and Copilot-style assistants retrieve documents from one silo and summarise them for you. An operational context layer sits across the systems of record (chat, tickets, wiki, CRM, mailbox, meeting notes), decides which item is current and for whom, cites the passage that put it in front of you, and turns it into an action a named person approves. It answers "what is the state of this customer right now, and what do I do about it", which no single system's digest can.
How is every answer trimmed to what the asker is allowed to see?
The layer never holds permissions of its own. Every read runs delegated, with the signed-in person's own permissions in each system, and membership is resolved from the company's own directory groups at question time. A hit the asker may not open is dropped without a count, so a meeting title or a chat never leaks through a summary or a provenance chain.
What does "human-approved actions" guarantee in practice?
A proposed write is staged as pending and posted as a card in chat. The proposed external action waits until a person taps Approve. Separately, meeting-derived facts and their sharing can use scoped standing consent recorded on each fact. That holds on every door, including the MCP door an editor or assistant connects to: an assistant can propose, it cannot accept. The same message never opens a second review, and the same signal from a second message never does either.
How does a fact reach the knowledge graph, and who signed for it?
Only through a person's verdict or a person's standing consent. The review queue: one row per claim, one verdict per row, by the person. Sharing: consent a person gives once for decisions from their own meetings, and it is recorded on every fact it produces. Nothing the layer merely reads ever lands on the graph.
Which data is excluded by design?
HR and personal data are excluded in depth, from the source scope through the schema to the audit trail. Commercial terms (day rates, margins, discounts, contract values) and anything about somebody's employment never travel, even when sharing is on. Meetings with an external participant are refused. Transcripts are read live and never stored, only the write-up is.
Where does it run, and what about data residency?
Compute, storage and language-model inference all run in the EU, on the company's own cloud tenant. The models are OpenAI models in Azure AI Foundry, deployed so that prompts and responses are processed only inside the EU. The review document names each model with its deployment, because a security review will ask exactly this question.
What is different from the digests built into the big suites?
Those summarise one system's content and send it to you, per silo. The context layer folds six sources by customer, cites the mention or drops the item, puts a colleague's signed fact and the recorded decision on the team's radar with the chain behind it, lets you act where the change lives as yourself, and shows the deal next to the engineering work behind it.
Can I use it from Claude, Codex or another MCP-enabled application?
Yes. The MCP door exposes the same governed backend to Claude (Cowork, Desktop and the claude.ai custom connector), Codex and any MCP-enabled application. The caller's identity travels with the call, so every answer is trimmed to that person, an assistant can propose into the Proposals tab and cannot accept, and every call lands in the same audit trail as the chat tab.
What happens in the architecture review?
A review, in a set number of hours, of the write path of the agents you already run: the routing rules that decide what is allowed to become true, and the measured ratio of what reaches a human today versus what should. The detailed architecture behind this page (identity resolution, permission mapping, supersession rules, schemas and prompts) is shared in that review, after we know who is asking and why.
Stack Stack
- Chat bot with approval cards and tabs for the change radar and the Proposals tab
- Runs on the company's own cloud tenant in the EU
- Delegated access only: every read and every write as the signed-in person, no service account
- Typed records with provenance on every record, an append-only audit trail, gap telemetry from day one
- MCP door for Claude, Codex and MCP-enabled applications, with the same identity, the same gate and the same audit trail
Ähnliches Projekt auf dem Tisch? Similar project on your desk?
Am schnellsten klärt das ein Gespräch. Termin direkt hier wählen: The fastest way to scope it is a conversation. Pick a slot right here:
Your agents answer from whatever the retriever finds, and too often that is last quarter's truth. I build the context layer they answer and act from: a temporal knowledge graph that keeps every fact with its source and the time it held, reads with each person's own permissions, and writes nothing without a person's approval. On your own tenant, billed by the hour, step by step.