Blog
Engineering notes on AI agents, automation, and the infrastructure behind them.
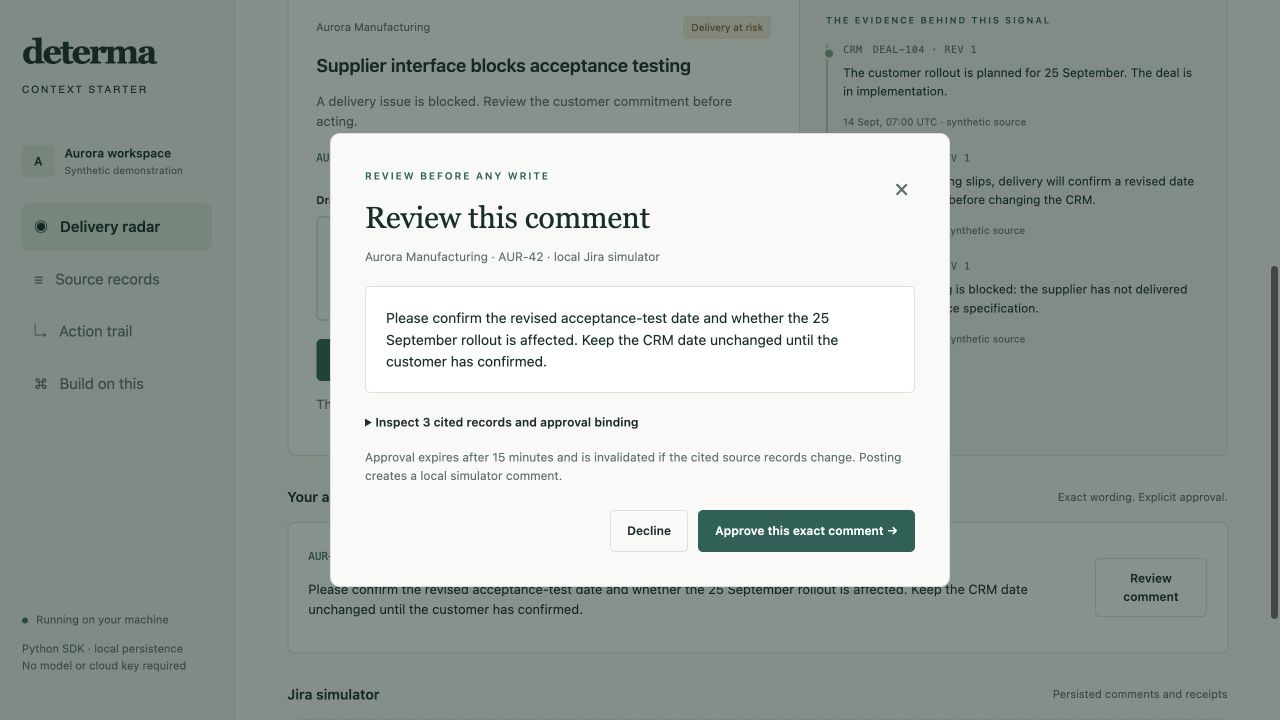
Palantir Foundry Alternative: Start With One Workflow
Compare Palantir Foundry with a focused open-source context layer: scope, costs, governance and a runnable delivery-blocker demo.
Temporal Knowledge Graph: How AI Agents Know What Is True Now
A temporal knowledge graph stores every fact with when it held and when it was recorded. How it works for AI agents, how Graphiti builds it, and when to use one.
Graphiti vs Mem0: Which Memory Layer Fits Your AI Agents
Graphiti vs Mem0 in September 2026: how each stores and updates facts, what runs self-hosted, what the benchmark fight says, and which fits your agents.
Graphiti in Production: FalkorDB or Neo4j, Azure or Ollama, and What Breaks
Running Graphiti in production: FalkorDB or Neo4j, Azure OpenAI or Ollama, embedding widths, version pins, ingestion cost and the failures to watch for.

Claude API Pricing Tiers and Cost Optimization Playbook (2026)
Claude API and Fable 5 pricing, plus every lever to cut Anthropic API cost without losing quality: routing, caching, batching, effort tuning.
Claude Fable 5 Cost: What It Actually Costs and How to Control It (2026)
Claude Fable 5 and 5.1 cost $10/$50 per million tokens, twice Opus 5. Cache reads fell to $0.25 on 5.1. What drives the bill and how to govern it.

Voice AI Agents for Small Business: What Actually Ships in 2026
The voice AI that pays back for a small business is narrow and boring: after-hours triage, booking, order status. Here is what ships and what to skip.
Agent Memory From Your Task Manager: CLI + MCP, No Vector DB
Turn your task manager into agent memory: an adapter-not-migration CLI and MCP server with hybrid RRF retrieval over TickTick or an Obsidian vault.

Pinecone vs RunPod for Vector Search: Managed vs Self-Hosted (2026)
Pinecone vs RunPod for vector search: managed serverless against self-hosted Qdrant on a rented pod. Sep 2026 prices, break-even, residency.
Pinecone vs RunPod: They're Not Competitors (2026)
Pinecone vs RunPod: a vector database and a GPU cloud, not rivals. Sep 2026 prices, EU regions, and when Qdrant on RunPod replaces Pinecone.

Automate YouTube Shorts with CapCut: The CLI + Claude Pipeline
Automate YouTube Shorts end-to-end: pick segments, write hooks with Claude, build CapCut drafts via CLI. Open-source pipeline + my paid blueprint.

Claude Code with Local LLMs and ANTHROPIC_BASE_URL: Ollama, LM Studio, llama.cpp, vLLM
Run Claude Code on a local LLM via ANTHROPIC_BASE_URL. Native Anthropic endpoints for Ollama, LM Studio, llama.cpp, vLLM. 32K context floor.
The context layer for your AI agents
Your agents answer from whatever the retriever finds, and too often that is last quarter's truth. I build the context layer they answer and act from: a temporal knowledge graph that keeps every fact with its source and the time it held, reads with each person's own permissions, and writes nothing without a person's approval. On your own tenant, billed by the hour, step by step.